- What changed
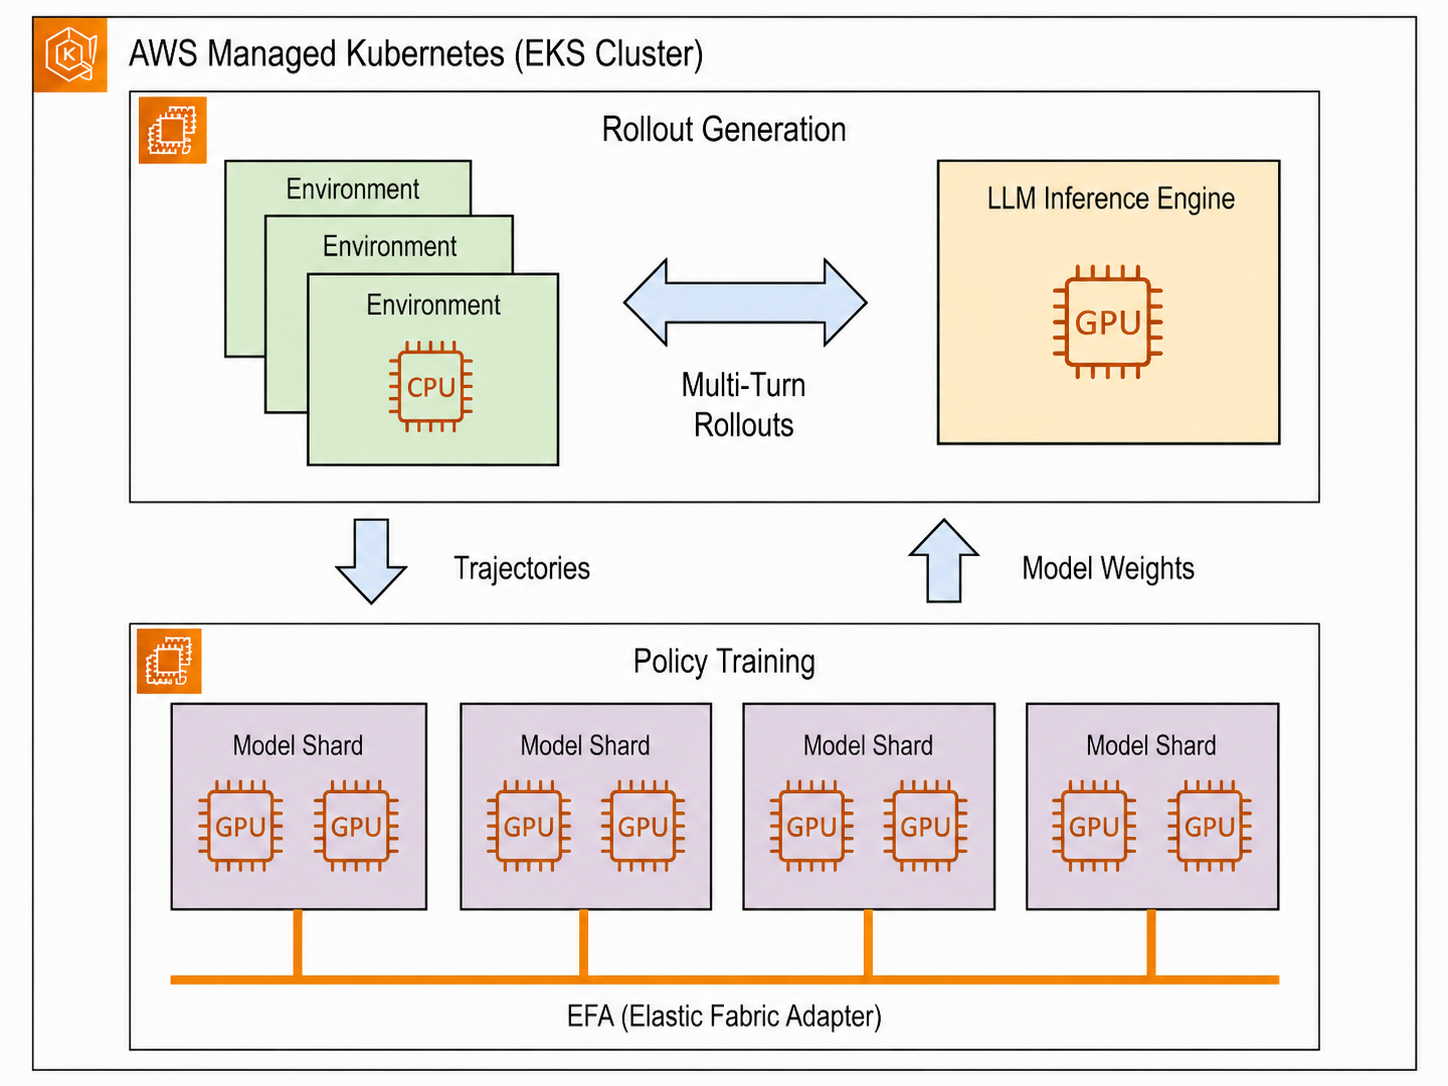
- AWS published an architecture pattern using Amazon EKS, EFA, and DeepEP to scale Mixture-of-Experts reinforcement learning post-training with reported throughput gains.
- Why you should care
- Scaling MoE reinforcement learning requires coordinating heterogeneous compute and maintaining high-throughput communication across accelerators.
- Your move
- Watch. Monitor whether these infrastructure patterns become standard deployment templates for large-scale training.
- What to watch next
- Independent benchmarks or case studies confirming the reported throughput gains in production environments.
- Event
- improvement
- Event date
- Sep 25, 2026
- Relevant to
- General AI readers