Open weights, local inference, and the models you can run yourself.
10 of 11 stories
New Tech
A contributor shared benchmark data for an optimization in llama.cpp using const references in the ngram cache drafting loop, showing significant latency and memory improvements on an Apple M4 Pro CPU.
Why it matters: Optimizing memory copying overhead in local inference runtimes directly improves execution speed on consumer hardware.
Keep watching Monitor repository updates to see if the proposed cache optimization is merged into the main release.
GitHub
Hacker News — LLM · 5h ago
Companies
Chinese AI models have gained significant global adoption on developer platforms due to lower prices and strong performance, prompting heightened regulatory scrutiny in Washington.
Google
CNBC — Technology · 1d ago
New Tech
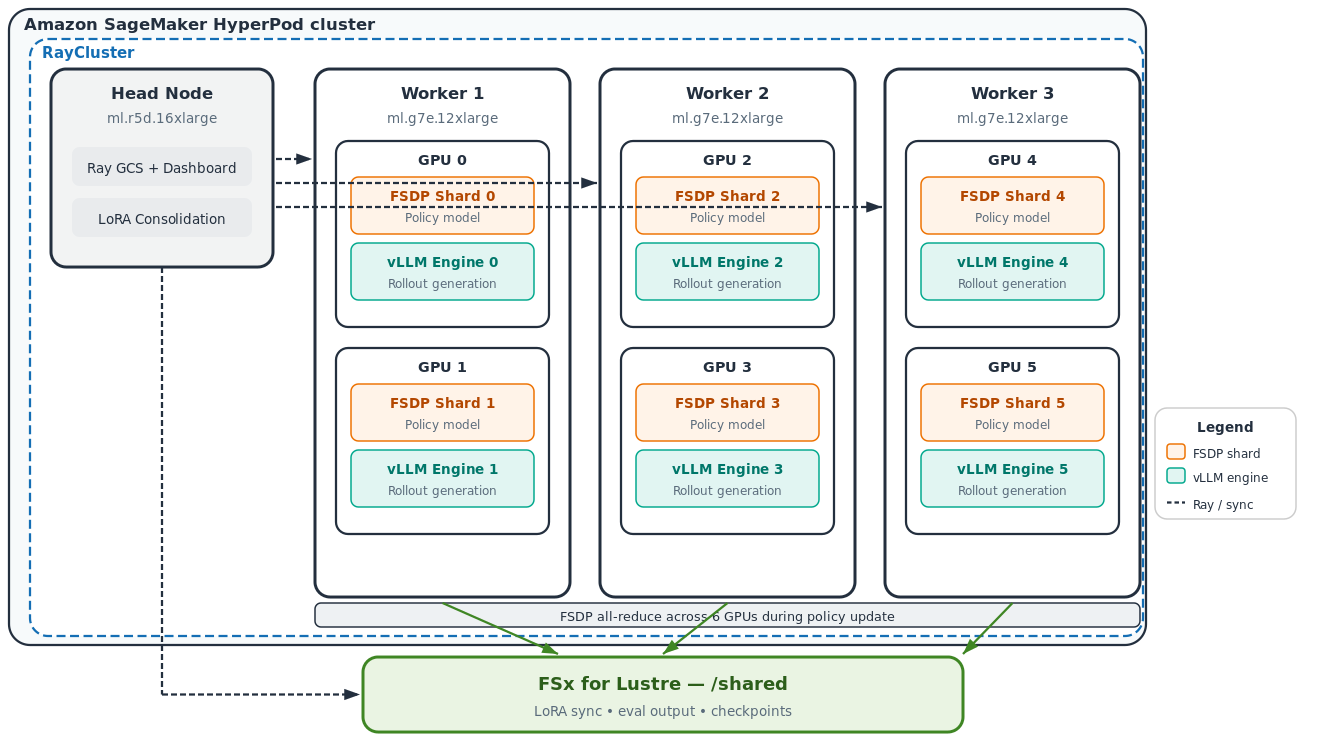
AWS demonstrates using SkyRL and Amazon SageMaker HyperPod to run reinforcement learning post-training for the Qwen3-VL-8B vision language model using Group Relative Policy Optimization.